Why build one
Reading about model serving is not the same as being paged by it. Glasshouse exists so that every part of an inference platform — routing, batching, KV-cache pressure, GPU scheduling, GitOps — can be broken on purpose and fixed with the graphs open.
Shape
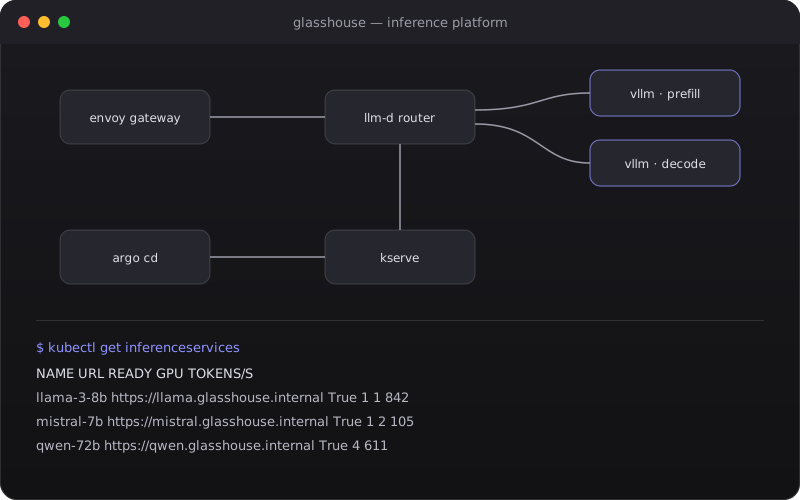
- Envoy Gateway at the edge, with per-model rate limits.
- llm-d for prefill/decode disaggregation and KV-cache-aware routing.
- vLLM as the engine, one InferenceService per model via KServe.
- Argo CD applying everything from a single Helm chart per environment.
What it taught me
Most of what is in the GPUs on Kubernetes series. The short version: the scheduler’s integer, allocated-versus-busy, and the fact that the cheapest GPU is the one you did not have to add.